Results
Architectural compliance engines reproduced
ARCH-EGRESS-001 and ARCH-SPATIAL-001 evaluated on 22 procedurally generated IFC scenarios covering egress
travel distance, storey exit count, emergency escape windows, daylight glazing ratio and fire-separation
rating. The benchmark is deterministic and hermetic; ground truth comes from the generator
(eval/generate_arch_test_models.py), not from human labelling.
| Metric | Point Estimate | 95% Wilson CI | TP / FP | FN / TN | Total Cases |
|---|---|---|---|---|---|
| Accuracy | 100.0% | [85.1%, 100.0%] | 13 / 0 | 0 / 9 | 22 |
| Sensitivity / Recall | 100.0% | [77.2%, 100.0%] | — | — | 13 Positives |
| Specificity | 100.0% | [70.1%, 100.0%] | — | — | 9 Negatives |
| Precision | 100.0% | [77.2%, 100.0%] | — | — | 13 Flagged |
| F1 Score | 100.0% | [77.2%, 100.0%] | — | — | — |
| Balanced Accuracy | 100.0% | [73.6%, 100.0%] | — | — | — |
Source: table_2_arch_confusion_matrix.tex (generated by eval/generate_publication_artifacts.py)
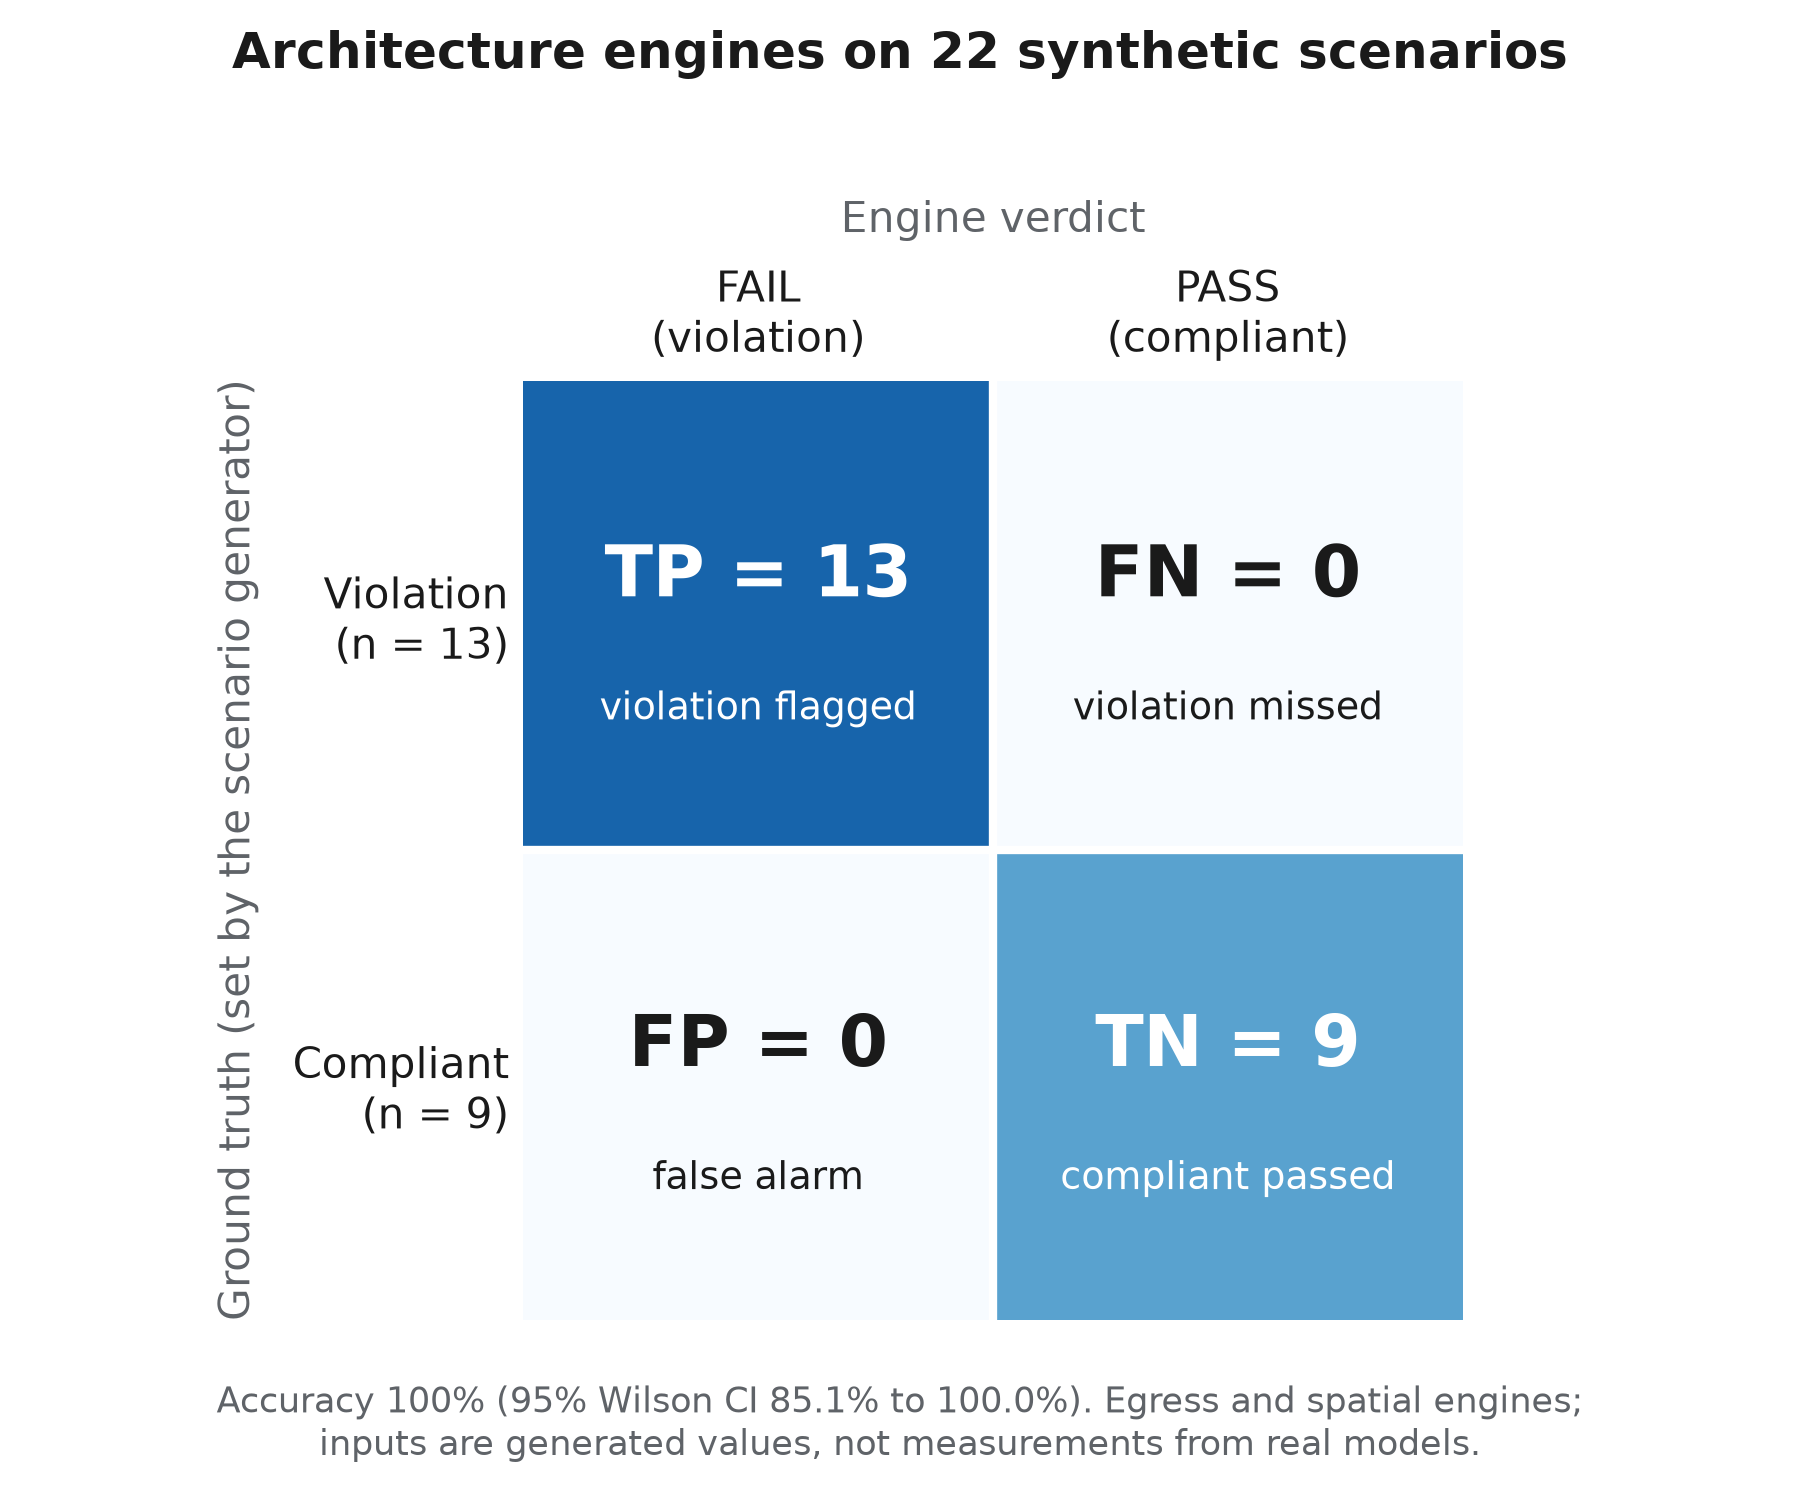
How to read this. 100% on 22 cases is a statement about these cases. The Wilson interval, with a lower bound of 85.1% for accuracy, is the honest summary of what the sample supports. Because the ground truth is synthetic, it shows the engines implement the rules as specified, not that the rules match real-world inspector judgement. Replacing it with human labels is the next step (see Limitations).
Claim and artifact: §7 of the claims ledger.
Extraction evidence
The real rule-extraction evidence is the end-to-end run against the human-labelled OBC 9.8 gold set,
committed in
eval/results/e2e/. It has a
single annotator and no adjudication; see Limitations.
Simulated harnesses simulated
Not evidence. The tables below are kept so the repository's history is transparent, and because the harnesses are useful scaffolding for real data. Their inputs are generated by the scripts themselves, so the numbers are internally consistent but say nothing about BIM-Guard, human annotators or an LLM judge. Do not cite them as results. Details: claims ledger §5, §6 and §8.
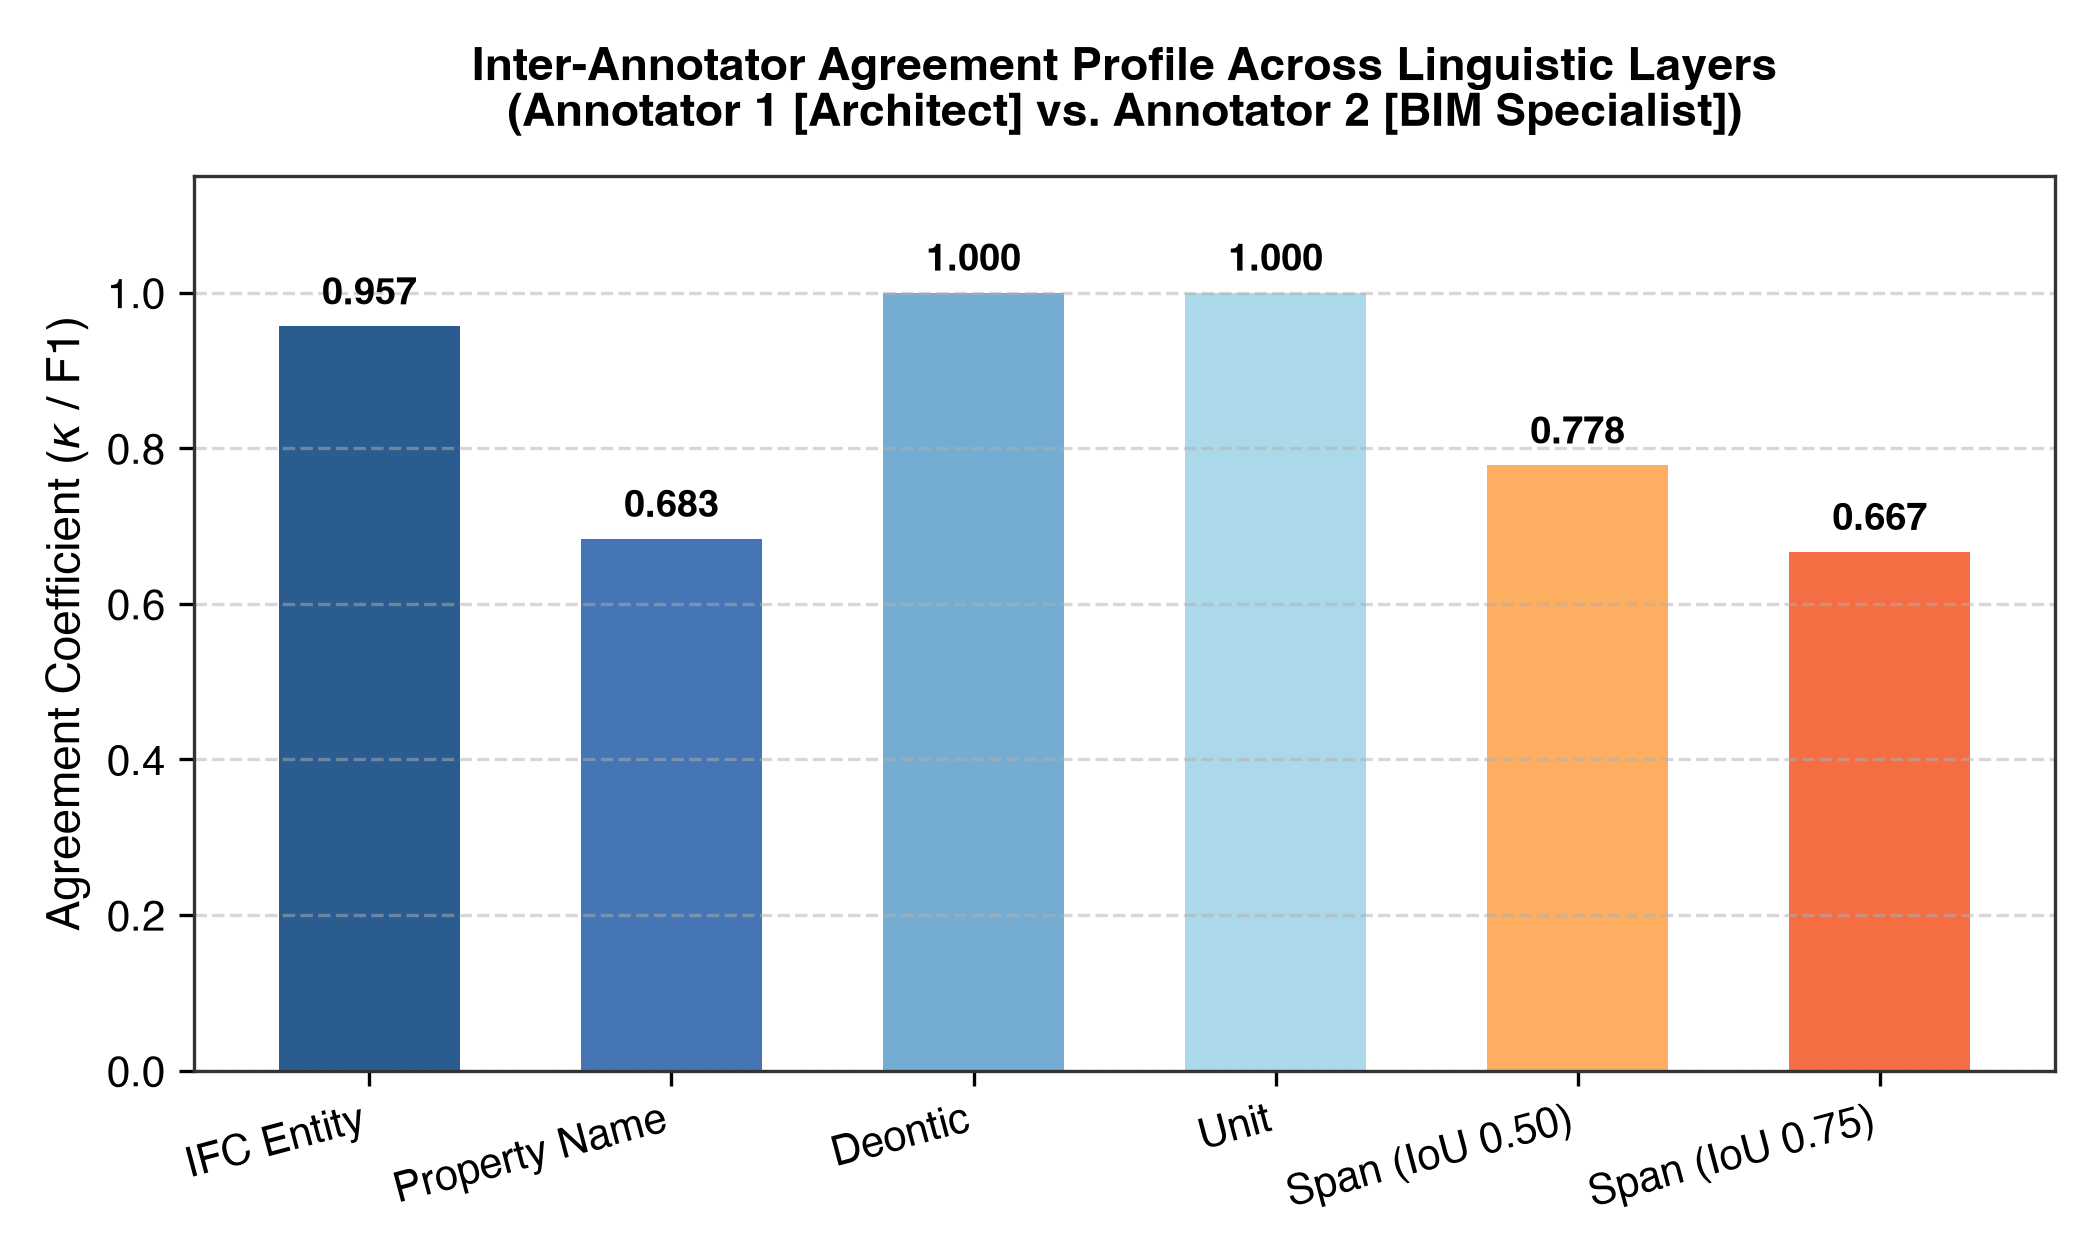
Inter-annotator agreement (simulated annotators)
The 30-task corpus is generated by research/annotations/generate_corpus.py with hard-coded labels for both
"annotators".
| Annotation Target | Cohen's κ (1 vs 2) | 95% Bootstrap CI | Fleiss' κ (Multi-Rater) | 95% Bootstrap CI |
|---|---|---|---|---|
| Target IFC Entity | 0.957 | [0.864, 1.000] | 0.971 | [0.909, 1.000] |
| Property Name | 0.683 | [0.506, 0.820] | 0.786 | [0.657, 0.879] |
| Deontic Modality | 1.000 | [1.000, 1.000] | 1.000 | [1.000, 1.000] |
| Measurement Unit | 1.000 | [1.000, 1.000] | 1.000 | [1.000, 1.000] |
| Span Extraction Metric | Precision | Recall | F1 Score | 95% Bootstrap CI |
| Span IoU ≥ 0.50 | 0.778 | 0.778 | 0.778 | [0.691, 0.824] |
| Span IoU ≥ 0.75 | 0.667 | 0.667 | 0.667 | [0.574, 0.722] |
Source: table_1_iaa_metrics.tex (generated by eval/generate_publication_artifacts.py)
Cross-jurisdiction generalization (simulated extraction)
eval/score_cross_code.py perturbs gold rules instead of running an extractor, so F1 = 100% is guaranteed by construction.
| Benchmark Metric | OBC 2024 (Part 9) | SBC-201-2007 (Chapter 8) | Generalization Gap (Δ) |
|---|---|---|---|
| Gold Standard Rules | 29 | 28 | Balanced Sample |
| Target IFC Entity Accuracy | 100.0% | 100.0% | Δ = 0.0% |
| Operator Extraction Accuracy | 100.0% | 100.0% | Δ = 0.0% |
| Precision [95% CI] | 100.0% | 100.0% | Δ = 0.0% |
| Recall / Sensitivity [95% CI] | 100.0% | 100.0% | Δ = 0.0% |
| F1 Score [95% CI] | 100.0% | 100.0% | \mathbf{Δ F_1 = 0.0000} |
Source: table_3_cross_code_generalization.tex (generated by eval/generate_publication_artifacts.py)
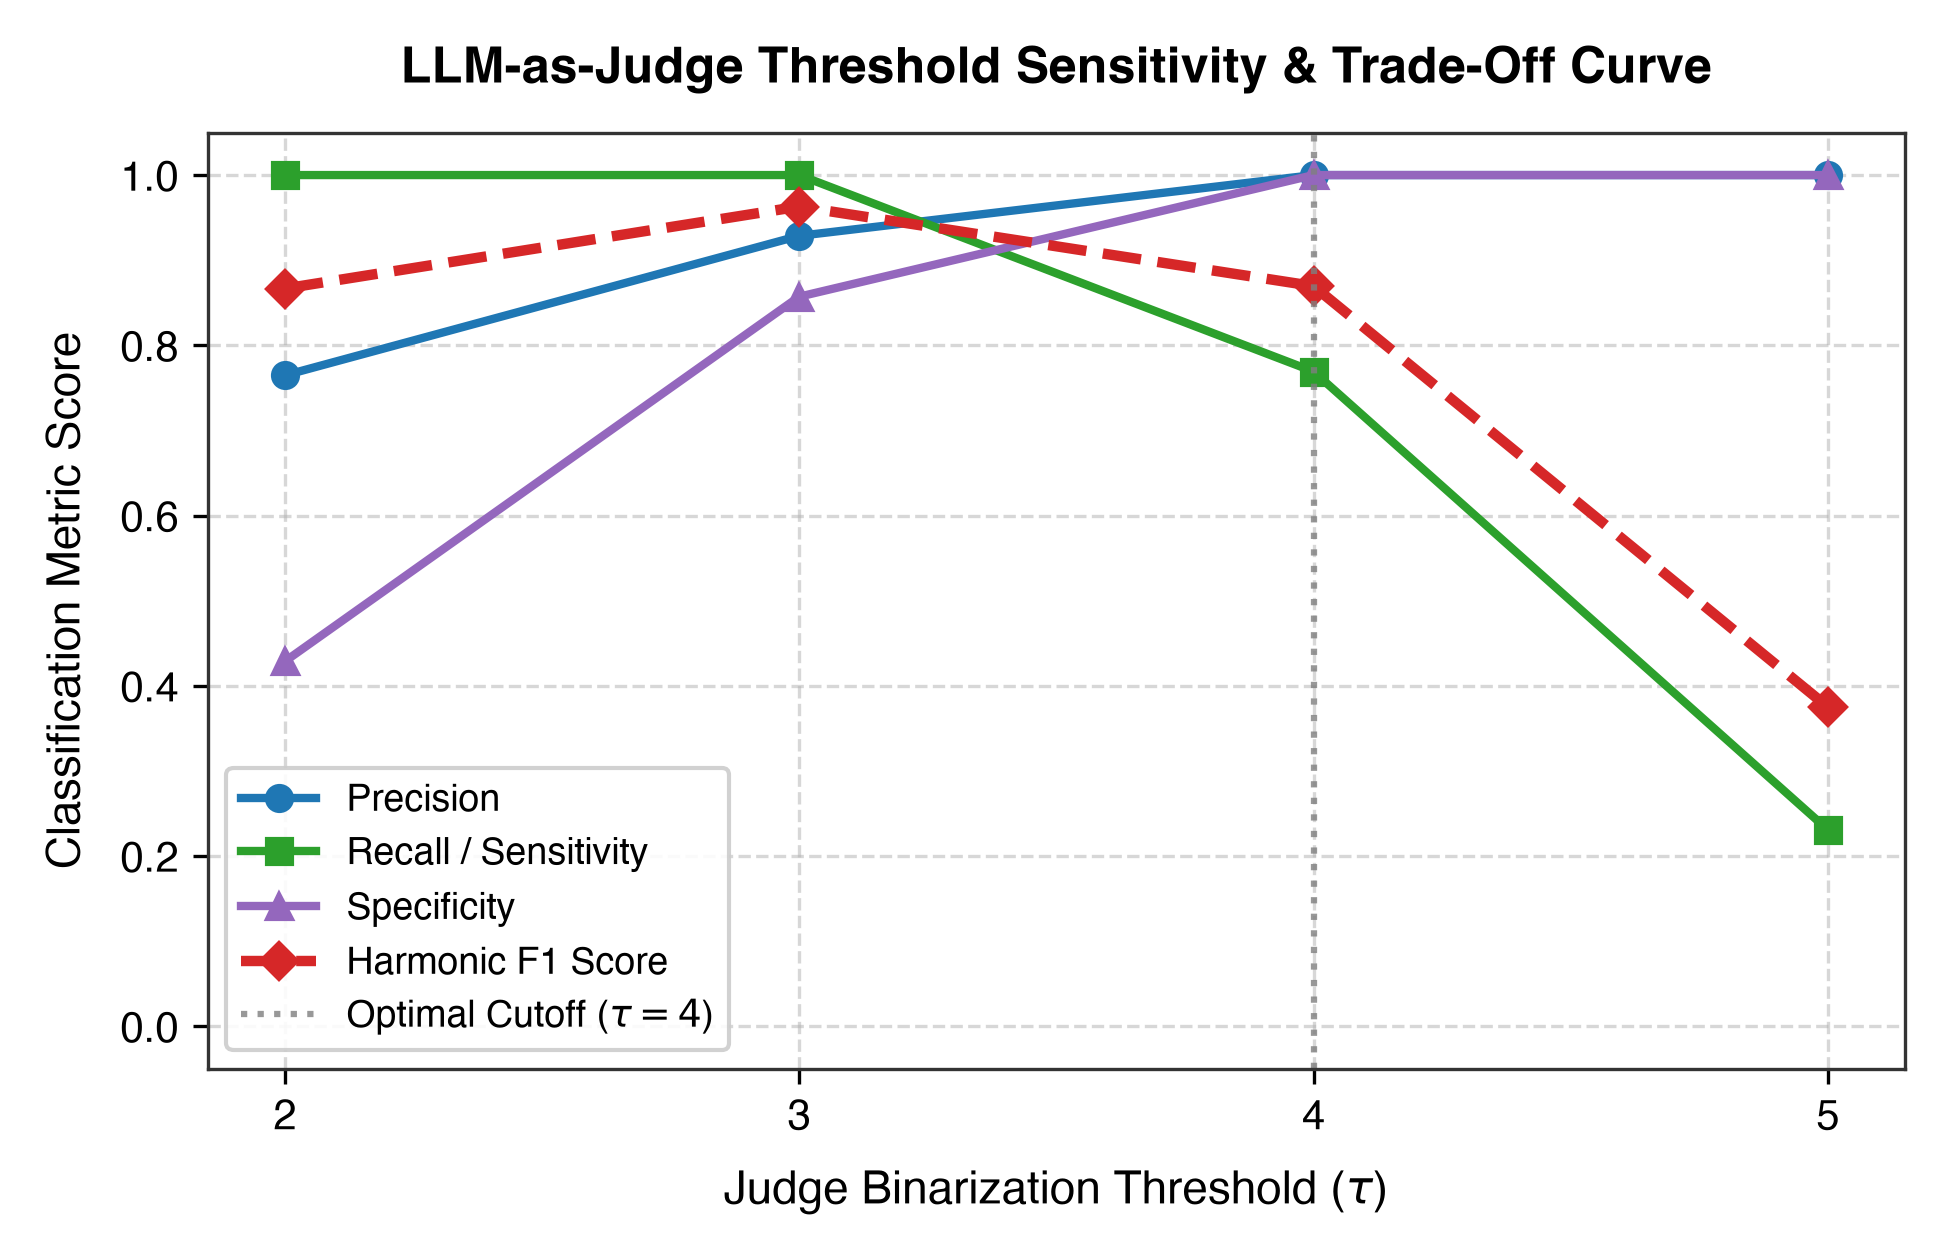
LLM-judge threshold sweep (hard-coded ratings)
eval/score_judge_sensitivity.py scores hard-coded judge ratings. It does not show that τ = 4 is optimal.
| Cutoff | TP | FP | FN | TN | Precision | Recall | Specificity | F1 Score |
|---|---|---|---|---|---|---|---|---|
| τ = 2 | 13 | 4 | 0 | 3 | 76.5% | 100.0% | 42.9% | 86.7% |
| τ = 3 | 13 | 1 | 0 | 6 | 92.9% | 100.0% | 85.7% | 96.3% |
| τ = 4 | 10 | 0 | 3 | 7 | 100.0% | 76.9% | 100.0% | 87.0% |
| τ = 5 | 3 | 0 | 10 | 7 | 100.0% | 23.1% | 100.0% | 37.5% |
Source: table_4_judge_sensitivity.tex (generated by eval/generate_publication_artifacts.py)